OpenAI Whisper: what it is, how to use it, cost
Whisper is OpenAI's free, MIT-licensed speech-to-text model. How to run it locally, which model to pick, API prices and its known limits.


OpenAI Whisper is an open-source speech recognition model. It turns speech into text in many languages and can translate non-English speech into English. The code and model weights are free under the MIT License (GitHub), so you can run it on your own machine with pip install -U openai-whisper and ffmpeg. If you don't want to run it yourself, OpenAI's API hosts it as whisper-1 at $0.006 per minute, next to newer transcription models such as gpt-transcribe at $0.0045 per minute (OpenAI pricing, as of September 2026). Two things to know before you start: open-source Whisper does not label speakers, and it sometimes writes text that was never spoken.
Whisper at a glance
| Fact | Detail |
|---|---|
| Made by | OpenAI |
| First release | September 2022; large-v2 in December 2022, large-v3 in November 2023, turbo in September 2024 (model card) |
| License | MIT, for both code and weights |
| What it does | Transcription, speech translation to English, language identification |
| Training data | 680,000 hours of audio: about 65% English, with the non-English audio covering 98 languages (model card) |
| Latest pip release | 20250625 (PyPI) |
| Hosted version | whisper-1 in the OpenAI API, $0.006/minute |
Whisper models: which one to pick
The open-source release comes in six sizes. This table is from the README; speeds are relative to large, measured on English speech on an A100 GPU, and your hardware will differ.
| Model | Parameters | English-only version | VRAM needed | Relative speed |
|---|---|---|---|---|
| tiny | 39 M | tiny.en | ~1 GB | ~10x |
| base | 74 M | base.en | ~1 GB | ~7x |
| small | 244 M | small.en | ~2 GB | ~4x |
| medium | 769 M | medium.en | ~5 GB | ~2x |
| large | 1550 M | none | ~10 GB | 1x |
| turbo | 809 M | none | ~6 GB | ~8x |
The README lists turbo at 809 M parameters; the model card gives 798 M.
How to choose:
- turbo is the default in the command-line tool. The README describes it as an optimized
large-v3with faster transcription and minimal loss of accuracy. It is the right starting point for most transcription. - turbo is not trained for translation. If you pass
--task translate, it returns the original language. Usemediumorlargeto translate into English. - English-only
.enmodels tend to do better on English audio than the multilingual model of the same size, especially attinyandbase. - Accuracy varies a lot by language. The README links a word-error-rate breakdown by language for
large-v3andlarge-v2. Check your language before you commit to Whisper.
How to run Whisper locally
You need Python (the README says 3.8 to 3.11 are expected to work), PyTorch, and the ffmpeg command-line tool. A GPU helps a lot; on CPU, the larger models are slow.
- Install ffmpeg:
1# macOS (Homebrew)2brew install ffmpeg3 4# Ubuntu or Debian5sudo apt update && sudo apt install ffmpeg- Install Whisper:
1pip install -U openai-whisperIf the install fails while building tiktoken, the README says you may need Rust installed.
- Transcribe a file from the terminal:
1whisper audio.mp3 --model turboWhisper detects the language from the first 30 seconds. You can set it yourself, and translate with a multilingual model:
1whisper japanese.wav --language Japanese2whisper japanese.wav --model medium --language Japanese --task translateBy default the command writes every output format (txt, vtt, srt, tsv, json). Use --output_format srt for subtitles only, and whisper --help for the full list of options. Word-level timestamps are available as an experimental flag, --word_timestamps True.
- Or call it from Python:
1import whisper2 3model = whisper.load_model("turbo")4result = model.transcribe("audio.mp3")5print(result["text"])result["segments"] holds the timed segments, and result["language"] the detected language. The model files download on first use to ~/.cache/whisper.
How to use Whisper through the OpenAI API
If you don't want to manage a GPU, the speech-to-text API runs Whisper and newer models for you. As of September 2026:
| Model | Best for | Output formats | Price per minute |
|---|---|---|---|
gpt-transcribe | General transcription (OpenAI's current recommendation) | JSON | $0.0045 |
gpt-4o-mini-transcribe | Lower cost | JSON | $0.003 |
gpt-4o-transcribe | Transcription | JSON | $0.006 |
gpt-4o-transcribe-diarize | Speaker labels | diarized_json, JSON, text | $0.006 |
whisper-1 | Subtitles, timestamps, translation to English | srt, vtt, verbose_json, JSON, text | $0.006 |
Per-minute prices are OpenAI's estimates from its pricing page; some of these models are billed per token. Limits worth knowing, from the same guide:
- Uploads are capped at 25 MB per file. Supported types are mp3, mp4, mpeg, mpga, m4a, wav and webm. Longer recordings need to be compressed or split.
- Only
whisper-1returnssrt/vttand supports word or segment timestamps throughtimestamp_granularities.gpt-4o-transcribe-diarizedoesn't supporttimestamp_granularities, but itsdiarized_jsonsegments include start and end times. - The translation endpoint uses
whisper-1only and translates into English only. whisper-1prompts are limited to 224 tokens.
A minimal request that returns subtitles:
1curl https://api.openai.com/v1/audio/transcriptions \2 -H "Authorization: Bearer $OPENAI_API_KEY" \3 -F file="@audio.mp3" \4 -F model="whisper-1" \5 -F response_format="srt"How Whisper works
Whisper is a standard Transformer encoder-decoder, described in the paper Robust Speech Recognition via Large-Scale Weak Supervision. Audio is cut into 30-second windows and converted to a log-Mel spectrogram. The encoder processes the spectrogram, and the decoder predicts text along with special tokens that tell it which task to do: identify the language, transcribe, translate to English, or add timestamps. One model replaces what used to be several separate pipeline stages.
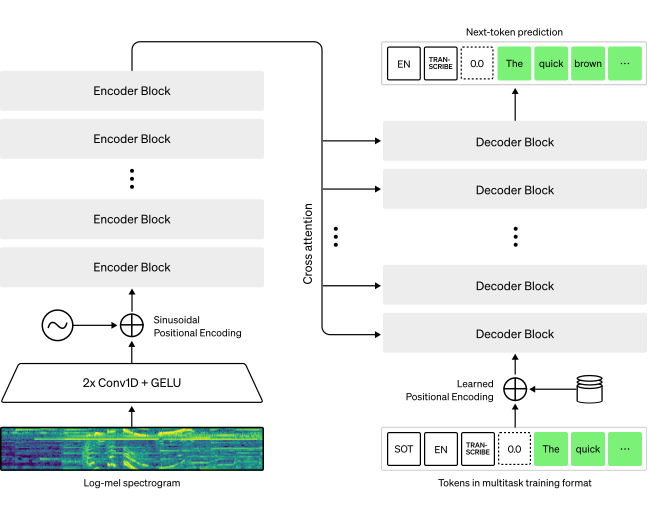
Image source: OpenAI
The difference from earlier systems was the data. Instead of training on small, carefully labelled datasets, OpenAI trained on 680,000 hours of audio paired with transcripts collected from the web, with a large share in languages other than English and a share used for translation to English.
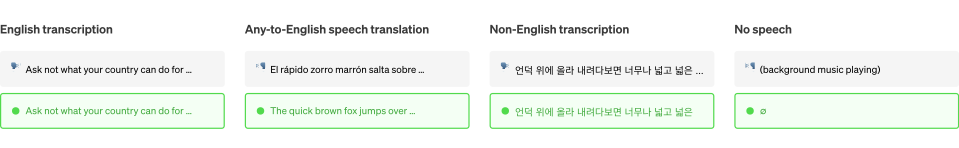
Image source: OpenAI
Known limits
- Hallucinations. The model card warns that output may include text not spoken in the audio. Users report this most often on silence, music or noise (see the GitHub discussion Hallucination on audio with no speech). Trimming silence or running voice activity detection first helps, and the CLI has a
--hallucination_silence_thresholdoption (it requires--word_timestamps True). - Repetition. The model card also notes the architecture can get stuck repeating text.
- Uneven accuracy. Performance is lower on low-resource languages and can differ across accents and dialects (model card).
- No speaker labels. Open-source Whisper gives you text and timestamps, not "who said what". On the API, speaker labels come from
gpt-4o-transcribe-diarize, notwhisper-1. - turbo won't translate, and API uploads stop at 25 MB.
- Not for high-stakes decisions. OpenAI cautions against using it in high-risk decision-making and against transcribing people recorded without their consent.
When a hosted tool makes more sense
Whisper is a model, not an app. Running it yourself means installing Python and ffmpeg, picking a model, having a GPU for speed, and then editing the raw text somewhere else. That is a good trade if you need privacy on your own hardware or you are building a product.
If you just need a transcript, subtitles or a summary, a hosted editor is less work. Disclosure: we make Exemplary AI. It transcribes audio and video in 99 languages in the browser, gives you a document-style editor where you can fix words and rename speakers, exports subtitles such as .srt, and can then translate, summarize or cut the recording into clips. There is a free plan; see pricing for limits.
Transcribe without the setup
Upload a file or paste a link and edit the transcript in your browser.
FAQ
Is OpenAI Whisper free?
Yes. The open-source Whisper code and model weights are free under the MIT License, including for commercial use; you only pay for your own hardware. The hosted whisper-1 model in OpenAI's API costs $0.006 per minute as of September 2026.
Which Whisper model is the best?
For English and most transcription, start with turbo: it is the CLI default, and the README describes it as an optimized large-v3 that is much faster with minimal loss of accuracy. Use medium or large if you need translation into English, and a .en model if you only transcribe English on limited hardware.
Can Whisper identify different speakers?
No. Open-source Whisper and whisper-1 return text and timestamps without speaker labels. OpenAI's gpt-4o-transcribe-diarize API model returns speaker-labelled segments, or you can use a transcription tool with speaker editing.
Does Whisper work offline?
Yes. After pip install -U openai-whisper downloads the package and the first run downloads the model file, transcription runs entirely on your machine.
What's the difference between Whisper and gpt-transcribe?
Whisper is the open model you can run yourself, and whisper-1 is its hosted API version with subtitle, timestamp and translation output. gpt-transcribe is a newer hosted-only model that OpenAI's speech-to-text guide recommends for general transcription; it returns JSON and costs $0.0045 per minute.
What is the file size limit for Whisper?
The OpenAI API accepts files up to 25 MB. Running Whisper locally has no fixed file size limit; long files just take longer and need enough memory.